DOCUMENT INTELLIGENCE

Turn Technical Documents into AI-Ready Knowledge.

Read Beyond the Text. Reveal the Information Inside.

AIKNOW Capture interprets tables, diagrams, formulas and the context across pages—not just individual characters. It brings document layout and content together, turning technical information into structured data for search, analysis and AI applications.

Challenges

Technical information extends beyond the text.

Design materials, technical reports, papers and specifications hold important information beyond their text.

01

Meaning is embedded in tables, graphs and formulas

Key conclusions and conditions are sometimes expressed not in sentences but in the structure of a table, the trend of a graph, a formula or the relationships within a figure.

Plain-text extraction can omit the relationships needed to interpret these elements.
02

Character recognition is one part of the process

OCR recognizes text in scanned pages and images.

Technical documents may also require layout analysis, table extraction and interpretation of figures. The processing and checks needed depend on the document and the intended use.

03

Digitizing does not create knowledge

Converting PDFs and images to plain text can discard document structure and relationships between elements.

Missing structure can make relevant information harder to retrieve and interpret in retrieval-augmented generation (RAG) applications.

Even when documents are stored and searchable, engineers may need to inspect several files to find the relevant technical context. Structured extraction can complement existing document management and search systems.

Complex Document Understanding

Extract document elements and preserve their context

AIKNOW Capture analyzes page layout and relationships between document elements.
It uses document structure and cross-page context to organize extracted information for downstream use.

Complex Layout

Analyzes complex layouts

Recognizes headings, multiple columns and annotations in reports and academic documents.

Identifies reading order and information structure to organize extracted text.

Cross-Page Context

Connects content across pages

Links related content that continues across columns or pages.

Uses document-level context to interpret those connections.

Document Structure

Recognizes document structure

Identifies chapters, sections, lists, quotations and footnotes, and organizes the data while preserving their hierarchy.

Tables & Formulas

Analyzes complex tables and formulas

Extracts table content and structure, including merged cells and checkbox states.

Extracts formulas from mathematics, physics, chemistry and other fields, and can also output them in LaTeX.

Multimodal Content

Beyond text: figures, images and design drawings

Analyzes figures, graphs, images and design drawings alongside the surrounding text.

Uses image correction and OCR to process text in faded or skewed images. Recoverable detail depends on the source quality.

Multiple File Formats

Supports many file formats

Supports PDF, Word and Excel documents.

Processing requirements depend on the file content, layout and quality, including whether the material is scanned or digitally generated.

Document Intelligence

Combine text recognition with document analysis.

The comparison below contrasts a text-only extraction workflow with AIKNOW Capture’s multimodal processing. OCR is also part of AIKNOW Capture’s pipeline.

Text-Only Extraction

Reads characters

Document Character recognition Text

This workflow produces recognized text.

If the output is limited to plain text, it may omit table structure, graph trends, links between figures and text, and relationships across pages.

Additional processing may be needed to recover these relationships for the intended application.

AIKNOW Capture

Structures document content

Document Visual understanding Structural understanding Semantic interpretation Knowledge

Analyzes text, tables and figures together and structures the extracted content and relationships for downstream use.

GenAI

Vision-language models

Processes images and text together to interpret varied layouts without requiring a fixed template for every document. Application-specific configuration and validation may still be needed.

Engineering

Document processing technology

Image correction and layout analysis prepare inputs for recognition. Post-processing uses matching, correction and confidence scoring to help identify inconsistencies, including in numbers and proper nouns.

Processing Pipeline

Turning documents directly into knowledge AI can use

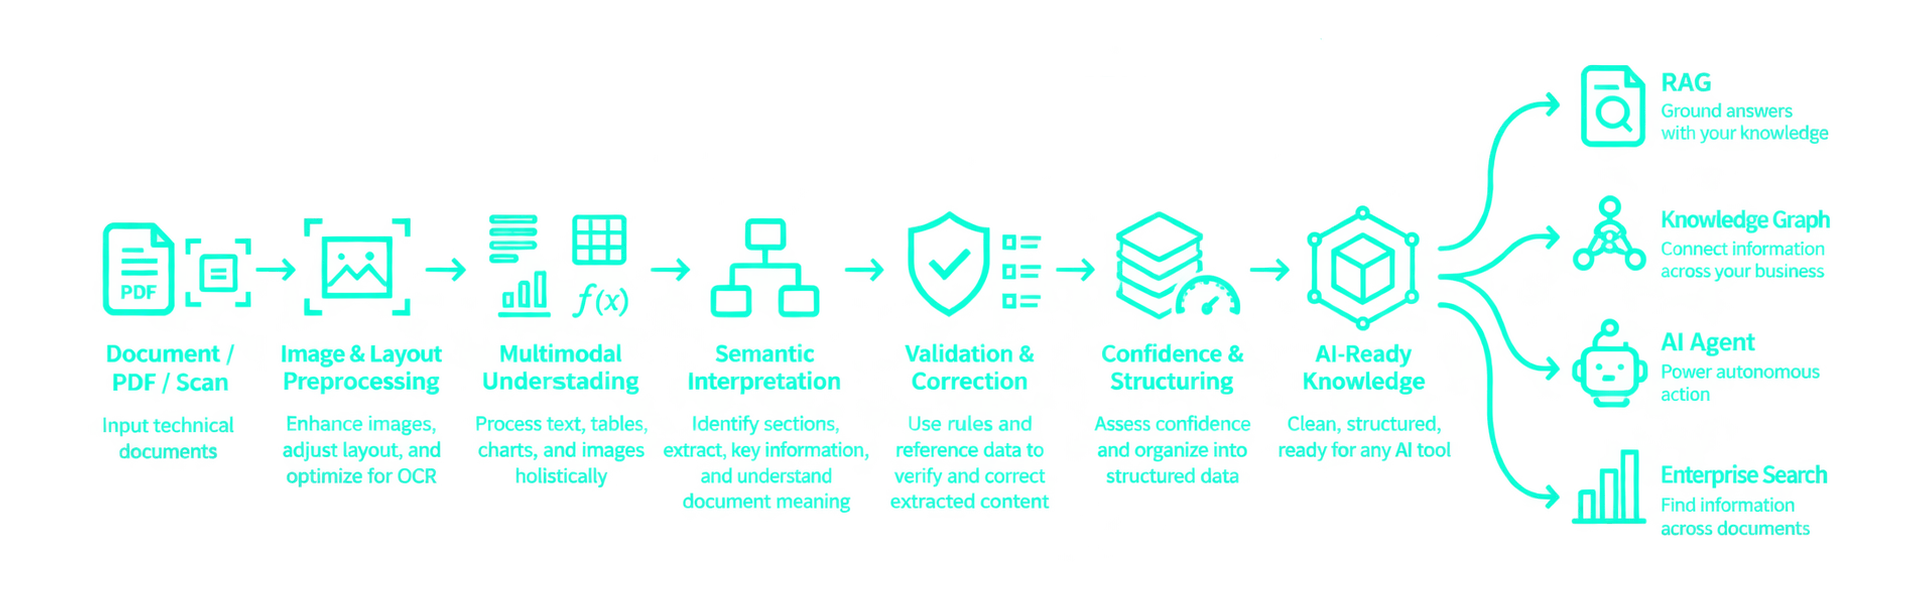
Five stages combine preprocessing, multimodal analysis, semantic interpretation, validation and structured output. Extraction quality depends on source quality, document complexity and processing configuration. Extracted results are automatically made available for downstream use without a mandatory review of each result. Quality requirements and any additional checks for the intended application should be assessed using representative documents during a POC.

The AIKNOW Capture document processing pipeline: Document / PDF / Scan (technical document input) → Image & Layout Preprocessing (image correction, layout adjustment, OCR optimization) → Multimodal Understanding (integrated processing of text, tables, graphs and images) → Semantic Interpretation (identifying chapter structure, extracting key information, understanding the document’s meaning) → Validation & Correction (verification and correction against rules and reference data) → Confidence & Structuring (confidence scoring and structuring) → AI-Ready Knowledge. The output connects to RAG, Knowledge Graph, AI Agent and Enterprise Search.

← Scroll horizontally →

Core Capabilities

Technology for understanding complex documents

Multimodal Document Understanding

Analyzes information beyond text

Information expressed in forms other than text is analyzed together, as part of the document.

VLM-Powered Recognition

Flexible document understanding with generative AI

Analyzes documents in different formats without fixed templates.

Japanese Document Processing

Built for Japanese documents

The recognition pipeline is designed for Japanese documents, combining OCR, a VLM, and pre- and post-processing.

It converts Japanese business and technical materials into a form that can be used as knowledge.

Pre & Post Processing

Pre- and post-processing for extraction quality

Includes image correction, alignment, matching and confidence scoring. Confidence scoring varies by document type and needs validation against representative documents during a proof of concept (POC); it should not be read as a guaranteed probability of correctness.

Parallel Processing

GPU and CPU processing

Recognition runs on GPUs, while preprocessing, matching and confidence calculation run in parallel on CPUs.

Throughput depends on hardware, concurrency and document complexity.

AI-Ready Structuring

Structured for use in RAG

Produces structured data that represents document elements and their relationships alongside extracted text.

The output supports integration with RAG applications, knowledge graphs and generative AI platforms. Output requirements and mappings depend on the target system.

Technology Performance

Internal benchmark on a handwritten form

In an internal test using a two-page handwritten form, the AIKNOW Capture configuration recorded approximately 30 times the page throughput per server of the reference configuration. The CPU and RAM configurations were the same; AIKNOW Capture additionally used an NVIDIA L40 GPU.

Internal Throughput Benchmark pages / sec / server
Reference configuration CPU
0.051
AIKNOW Capture CPU + L40 GPU
1.539

30× processing throughput (approx.)

Observed page throughput per server in this test.

Test scope: 20 runs using the same sample, a two-page form completed by hand. Both configurations used the same CPU and RAM configuration; the AIKNOW Capture configuration additionally used an NVIDIA L40 GPU. Reported throughput was 0.051 and 1.539 pages per second per server, respectively. The reference processing method, exact CPU/RAM specifications, concurrency, measurement date, aggregation method and output-quality criteria are not specified here. These figures describe this internal test, not a general performance or cost guarantee. They do not establish equivalent extraction quality or isolate the contribution of the processing software from the added GPU. Representative documents and deployment conditions should be evaluated in a POC.

Use Cases

Turning your accumulated technical documents into usable knowledge

Engineering Knowledge

Design and technical documents

Analyzes past design materials, specifications and test reports to build a knowledge base where engineers can find and reuse the technical information they need.

Technical Papers

Papers and research materials

Analyzes academic and technical documents that contain many figures, tables and formulas.

Research findings and technical information can then be used across sources.

Manuals & Specifications

Manuals and specifications

Structures product manuals and specifications with complex chapter structures, tables and figures.

Converts them into knowledge that RAG and AI assistants can use.

Legacy Documents

Legacy and scanned documents

Extracts and structures content from paper scans and legacy documents for downstream search, analysis and reuse. Poor image quality or missing detail can limit extraction.

From Document to Knowledge

Put technical document content
to work in your AI applications.

Discuss your document types, output requirements and target applications.
We can assess how AIKNOW Capture can prepare structured technical content for retrieval and reuse.

Talk to us about AIKNOW Capture